

For Reddit data inside a RAG pipeline, an agent or an LLM prompt, start with Scavio's Reddit API. Search posts with POST /api/v1/reddit/search, then pull each thread's full comment tree, nested replies included, with /api/v1/reddit/post/comments. That matters because the comments are where the answers are: in 14 threads we pulled on October 27, 2026, comments held 78% of the text. Every one of the 14 Reddit endpoints costs 1 credit, about $0.002 on the Growth plan billed yearly, with one API key and no Reddit app.
You may still want Reddit's own API, so here is where it stands. The Data API Terms, last revised July 20, 2026, grant no right to use Reddit content "for training a machine learning or AI model" without the rightsholders' permission, and require a separate agreement for commercial use. Reddit's Responsible Builder Policy, updated October 5, 2026, says you "must request access and get explicit approval before accessing any Reddit data through our API". For an approved non-commercial project, it is free.
We build Scavio, so read this with that bias in mind. Every Scavio number below comes from live calls we made on October 27, 2026. Every competitor detail was read off the vendor's own page or documentation that day, and where a price was not published we say so. The screenshots are each vendor's own Reddit page, captured the same day.
Which Reddit API fits your job?
| Tool | Choose it for | Comment trees | Access | Price (checked Oct 27, 2026) |
|---|---|---|---|---|
| Scavio | RAG, agents and LLM prompts that read threads on demand | Nested replies in tree order with depth; reply cursor for collapsed branches | One API key; no Reddit app, OAuth or approval | From $2 per 1,000 requests (Growth, yearly); 50 free credits |
| Reddit Data API + PRAW | Approved non-commercial projects | Full tree; PRAW's replace_more expands it | Request access, OAuth app; written approval for commercial use or AI training | Free tier, 100 queries a minute; commercial rate not published |
| Apify Reddit Scraper Lite | Scheduled exports of posts and comments to a dataset | Each comment stored as an item; maxComments cap | Apify account | From $3.40 per 1,000 results |
| Bright Data | Large files of post and comment records | Comments collector | Bright Data account | $1.50 per 1,000 records; 5,000 free records a month |
| SocialCrawl | Big threads where one call should return the whole tree | Nested tree in one call, 5 credits | API key | 100 free credits, then £15 for 2,500 to £299 for 150,000 |
The answer is in the comments, not the post
An LLM that reads only the Reddit post sees the question. We searched Reddit for "best embedding model for RAG" with Scavio, pulled every comment and reply on the 14 threads it returned, and counted tokens with the o200k_base tokenizer.
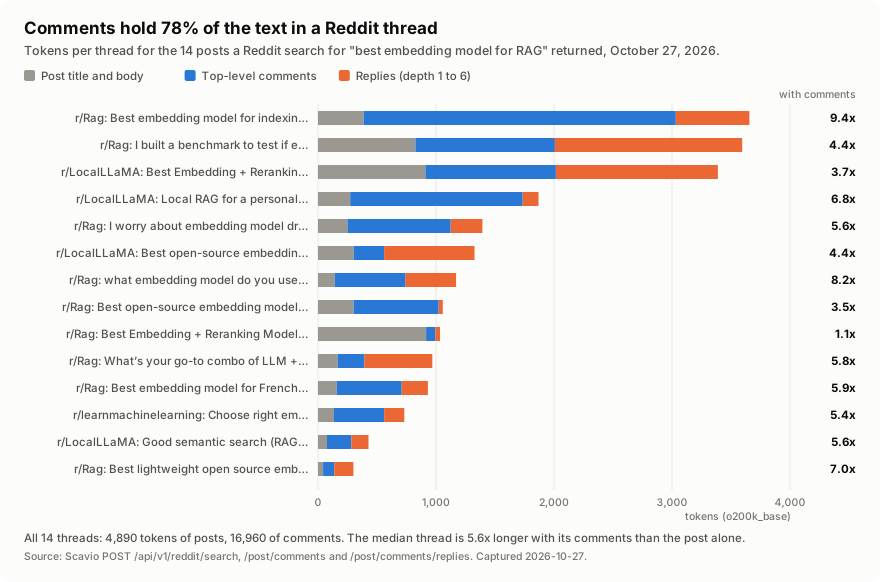
The 14 posts came to 4,890 tokens; their comments came to 16,960, 78% of everything. Replies below the top level, the part a "top comments only" pull drops, were 6,535 tokens, 30% of the total. The median thread was 5.6 times longer with its comments, and the largest, a 60-comment r/Rag thread on picking an embedding model for 17,000 scientific PDFs, went from 387 tokens of question to 3,656 with the answers. Only one thread, with 4 comments, was mostly post. If your agent answers "what do practitioners actually use", it needs the tree, and the tree still fits easily in a context window.
1. Scavio: search, feeds and the full comment tree for 1 credit a call
Scavio's Reddit API is 14 POST endpoints, each 1 credit. Measured on October 27:
- Search: "best embedding model for RAG" returned 7 posts a page in 3.4 s, each with
post_id, title, full bodytext, subreddit, author, score,upvote_ratio,num_commentsandcreated_at;next_cursorpages on. Comment search finds the replies that mention a term. - Post comments and replies: comments arrive in tree order with a
depthfield, about 8 a page, and nested replies come inline. Where Reddit collapses a branch, areply_cursorexpands it. The 14 threads took 45 calls (12 of them reply expansions), returned 243 comments, 127 of them replies down to depth 6, and answered in a median 1.7 s. - Subreddit posts: a community's feed by hot, new, top, rising or controversial, 6 to 7 posts a page. Feed rows carry title, score and comment count but no body, so add a post call when you need the text.
- Users, subreddits, suggestions, popular and trending: the other 8 endpoints, for vetting an account or finding the communities worth indexing.
What it does not do: pages are small, so a 60-comment thread is about 10 calls, and TOP on a subreddit feed is all-time, with no week or month window. The comment counts Reddit shows ran above what came back (277 against 243 here). It is a data API, not a Reddit licence, so how you use the content is still governed by Reddit's terms. The benefit is one key and one JSON format for Reddit alongside Google, YouTube and X, plus an MCP server whose Reddit tools an agent can call directly. How to get Reddit data into an LLM walks through each call with captured responses.
2. Reddit Data API with PRAW: free with approval, no commercial or training use without permission
Reddit's Data API Wiki, updated May 11, 2026, sets the free-access limit at 100 queries per minute per OAuth client id, averaged over 10 minutes, blocks traffic without OAuth, and requires you to delete posts, comments and user data once they are deleted on Reddit, recommending you purge stored user data within 48 hours. The Responsible Builder Policy requires approval before any access and explicit written approval for commercial use, and lists training "machine learning or AI models" among the uses that need it. Reddit publishes no commercial price; the $0.24 per 1,000 calls widely quoted comes from its 2023 pricing change and does not appear on its developer pages today.
PRAW, the Python wrapper behind the Reddit RAG tutorials that rank on Google (8.0.3, released August 12, 2026), needs a client_id, client_secret and user_agent from an approved app, and expands collapsed comment branches with replace_more(), each expansion counting against the same limit. Choose it if your project is non-commercial and approved: it is the official route and it costs nothing.
3. Apify Reddit Scraper Lite: scheduled dataset exports
trudax/reddit-scraper-lite had 50,200 total users and 8,413 monthly users on October 27. It scrapes posts, comments, communities and users by URL or keyword and is priced per event, from $3.40 per 1,000 results, lower on higher Apify plans. Its README says each post, comment, user or community is stored as a separate dataset item, so a 60-comment thread is 61 results; maxComments caps comments per post. Actors run as jobs that write to a dataset, which suits a nightly export into a vector store more than a per-question agent call. Each actor is maintained by its author, so pin the one you test.
4. Bright Data: bulk post and comment records
Bright Data's Reddit scraper URL now opens its Social Media Scraper API page, which lists Reddit post collectors (by subreddit URL, keyword or author) and a comments collector with comment id, text, date, post id and community. It costs $1.50 per 1,000 records pay-as-you-go, or $499 a month for 384,000 records with more at $1.30 per 1,000, and every account gets 5,000 free records a month with no card. Comments are records, so 1,000 comments cost $1.50. Choose it when the deliverable is a large file for a training-data pipeline you have cleared with Reddit, or a one-off corpus, rather than an answer inside a request.
5. SocialCrawl: the whole tree in one call
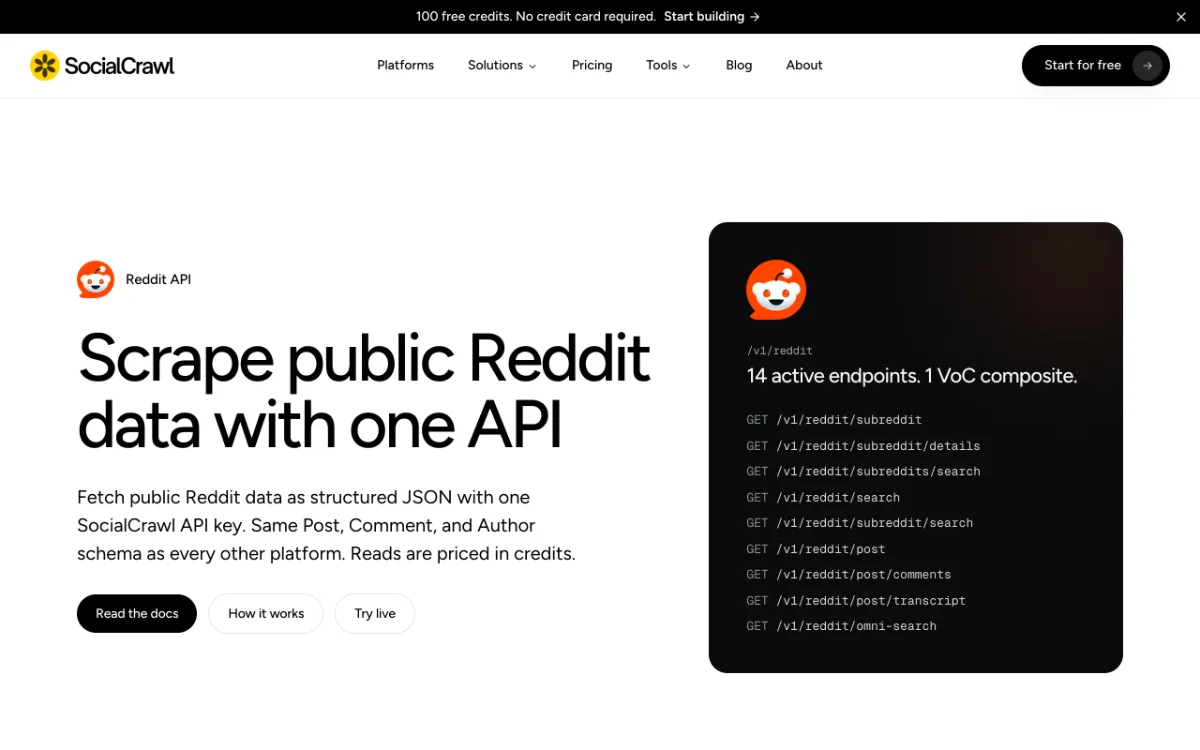
SocialCrawl's Reddit page lists 14 endpoints. Search, post and subreddit calls are 1 credit; post comments are 5 credits and return the full nested tree in one call, with a truncated flag and a replies cursor when Reddit cuts it short; an omni-search that expands threads is metered from 5 credits. Credits come in one-time packs that never expire: 100 free, then £15 for 2,500, £49 for 20,000 and £299 for 150,000 (prices shown in pounds when we checked). On a thread of 50 or more comments, one 5-credit call can cost less than paging; on the small threads that dominated our sample, which needed 1 to 3 Scavio calls, it costs more.
Data365 also sells Reddit data, from €300 a month for 500,000 credits, with a free trial that starts with a call; its Reddit page does not list comment endpoints. Several MCP servers wrap Reddit for agents, most of them on top of Reddit's own API and its approval rules.
Pick by the number you need
If your agent answers questions from what practitioners say on Reddit, fetching threads at question time and keeping the replies is the ongoing work, and it is what Scavio's Reddit API handles. A research agent that runs one search and reads the top 3 threads per question used about 1 + 3 x 3.2 = 11 credits in our sample (the 14 threads averaged 3.2 calls each). At 1,000 questions a month that is 11,000 credits: $22 at the Growth-yearly rate of $2 per 1,000 credits, or inside the 28,000 credits of the $100 monthly Bootstrap plan. Per comment, our 243 comments in 45 calls work out to about $0.37 per 1,000, against $1.50 at Bright Data and from $3.40 at the Apify actor, which bill each comment as a record. Try the Reddit API free, 50 credits, no card, or try the endpoints in the playground.
Reference: all 14 Reddit endpoints · post comments docs · what Reddit's API costs in 2026
Frequently asked questions
Can I use Reddit data with an LLM?
Reddit's own rules separate reading from training. Its Data API Terms, last revised July 20, 2026, grant no right to use Reddit content to train a machine learning or AI model without the rightsholders' permission, and its Responsible Builder Policy requires written approval for commercial use and for AI training. Retrieving public threads at question time for a RAG system or an agent is a different use, but you remain responsible for checking it against Reddit's terms with your own counsel.
Is the Reddit API free?
For approved non-commercial use, yes: Reddit's Data API Wiki lists 100 queries per minute per OAuth client id, averaged over 10 minutes. Since its Responsible Builder Policy, every app must request access and be approved first, and commercial use needs explicit written approval. Reddit does not publish a commercial rate card; the $0.24 per 1,000 calls figure dates from its 2023 pricing change.
Which Reddit API returns the full comment tree?
Scavio's post comments endpoint returns comments and their nested replies in tree order with a depth field, about 8 a page, and a reply cursor where Reddit collapses a branch. In our test of 14 threads it returned 243 comments, 127 of them replies, down to depth 6. SocialCrawl returns a nested tree in one 5-credit call, PRAW expands it with replace_more, and Apify and Bright Data store each comment as its own record.
How much Reddit data fits in an LLM context window?
Less than the comment counts suggest, because comments are short. Across 14 threads about embedding models for RAG, the posts were 4,890 tokens and the comments 16,960, so the median thread was 5.6 times longer with its comments. The largest thread, 60 comments, was 3,656 tokens, which fits in any current model's context.
What is the cheapest way to get Reddit comments for RAG?
Per comment, a per-call API. Scavio returned 243 comments in 45 calls, about $0.37 per 1,000 comments on its Growth plan billed yearly. Record-priced tools bill each comment: Bright Data is $1.50 per 1,000 records and the Apify Reddit Scraper Lite actor from $3.40 per 1,000 results. Reddit's free tier costs nothing for approved non-commercial projects.